The owner hears the same complaint before the morning meeting starts. Video calls freeze, cloud applications take several seconds to respond, and a shared drive seems unavailable even though every router light looks normal. Someone restarts the firewall, someone blames the internet provider, and the team loses time while troubleshooting follows instinct instead of evidence.
Network performance monitoring replaces that guesswork with continuous measurement. It shows whether the network is available, where performance is deteriorating, and how severe the problem has become. For a small business without a dedicated network operations center, that visibility can turn a disruptive incident into a manageable maintenance task.
Why Network Performance Monitoring Matters for Small Businesses
A large enterprise may have separate teams for infrastructure, security, applications, and service providers. A small business often has one generalist, an outside technician, or an office manager trying to determine why the accounting system is slow. That difference makes network problems more disruptive. One overloaded circuit, unstable wireless link, or failing switch port can affect nearly everyone at once.
Monitoring addresses the problems employees describe in everyday language:
- Dropped calls: Latency, jitter, and packet loss can explain why voice and video break up even when the connection remains technically online.
- Slow cloud applications: Historical response data helps separate a local network problem from an overloaded internet path or a SaaS dependency.
- Mystery outages: Availability records and event history show when a service became unreachable and whether the interruption came from the LAN, WAN, firewall, or provider.
- Recurring tickets: Trend data reveals patterns that individual complaints can't show, such as congestion at the same time each morning.
The discipline answers three practical questions before users have to escalate them: Is the service working? Where is performance breaking? How bad is it getting? Historical availability and round-trip time records are especially valuable because administrators can compare current behavior with earlier periods and correlate deterioration with network changes or outside events. That shift from reactive break-fix work to continuous measurement is described in reporting on the development of historical network performance monitoring.

Practical rule: A dashboard matters only when it helps a named person decide what to check next.
The business case also includes the cost of uncertainty. Owners evaluating downtime risk can use this explanation of the costly impact of downtime to connect technical interruptions with lost work, delayed service, and customer frustration. Monitoring doesn't prevent every failure, but it gives a small team a factual starting point and an earlier warning when normal behavior begins to change.
What Network Performance Monitoring Actually Does
Network performance monitoring is the ongoing collection and interpretation of signals from network equipment and user-facing systems. A monitoring platform may observe routers, switches, firewalls, wireless infrastructure, servers, cloud paths, and endpoints, then store the results so current behavior can be compared with a normal baseline.
A water-pipe analogy makes the measurements easier to understand. Bandwidth is the width of the pipe, or the maximum volume it can carry. Throughput is the amount moving through it. Latency is travel time. Packet loss is like a leak that forces some information to be sent again. Jitter is uneven pressure, where packets arrive at irregular intervals instead of smoothly.
The platform commonly gathers several kinds of evidence:
- Device metrics show interface usage, errors, CPU, memory, and availability.
- Flow records show which sources and destinations are exchanging traffic and how much they use.
- Synthetic tests send scheduled probes across important paths, such as an office to a cloud application.
- Endpoint measurements show the experience from a laptop or application host rather than only from a central device.
- Events and logs provide context for configuration changes, link transitions, firewall decisions, or VPN resets.
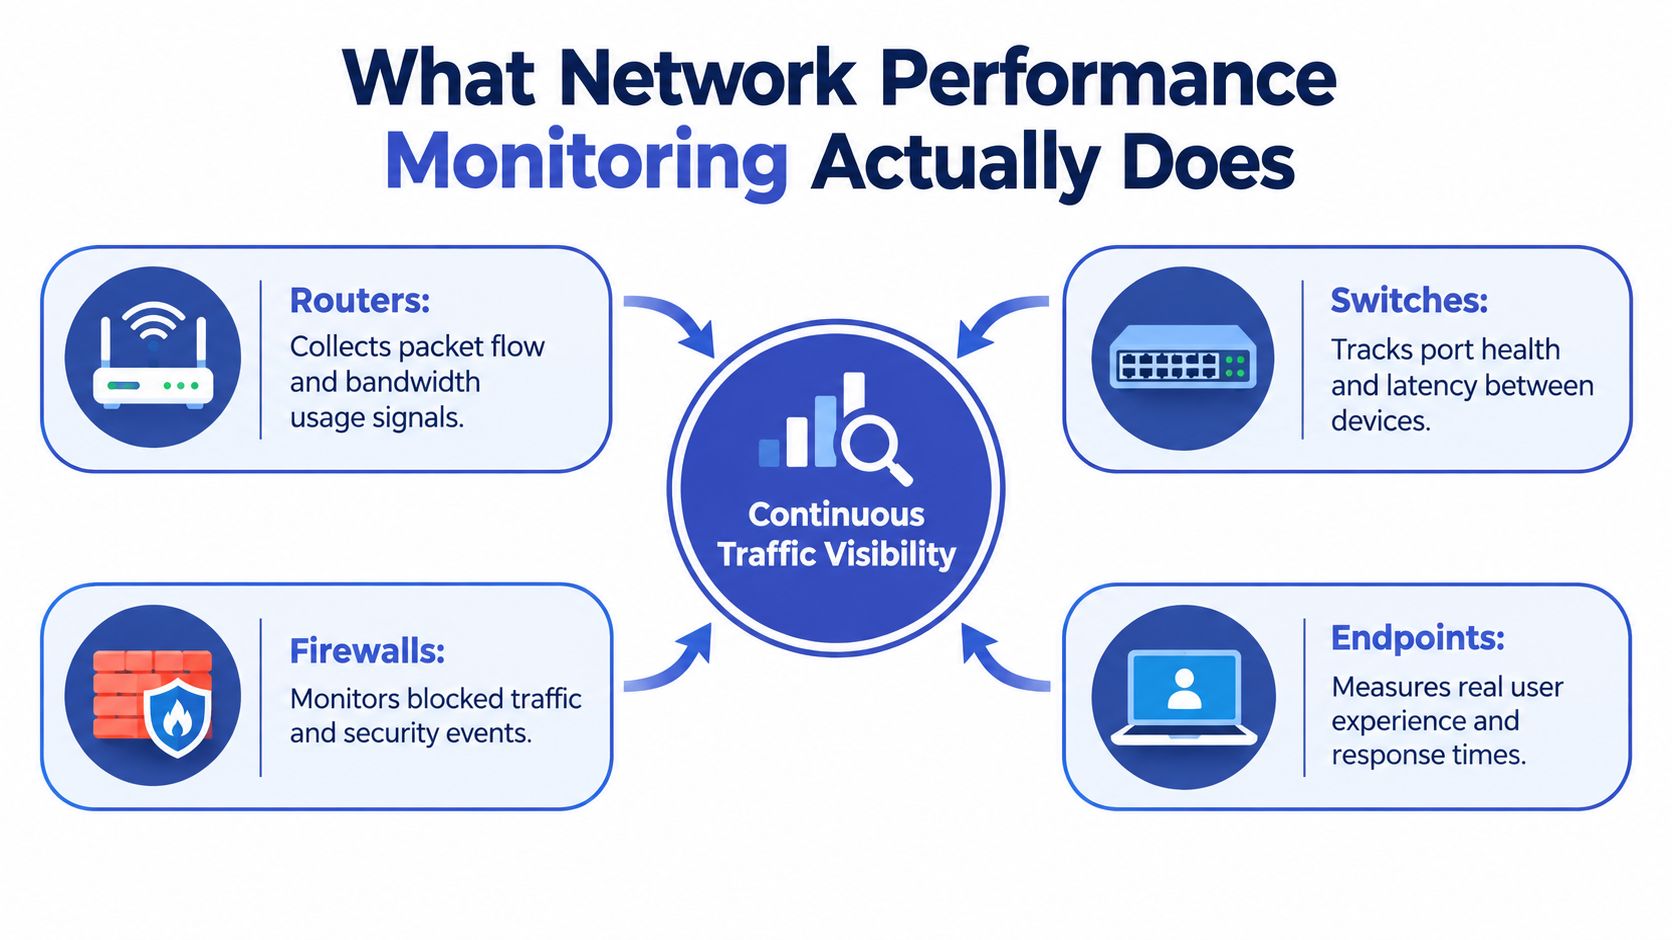
NPM isn't the same as a simple uptime check. An uptime check can confirm that a target responds, but it may not explain rising latency or congestion. Log management stores event messages for searching and investigation. Application performance monitoring focuses on application transactions and code behavior. Network performance monitoring sits between those views, measuring how infrastructure and paths carry traffic and, where possible, how users experience that delivery.
A small office may use SNMP, the Simple Network Management Protocol, to collect device counters, flow exports to identify traffic conversations, and synthetic probes to test important destinations. No single signal explains every incident. Together, they create a repeatable operating practice that replaces Monday morning fire drills with measured detection, focused diagnosis, and documented follow-up.
The Core Metrics That Reveal Network Health
Five measurements give an SMB a useful starting point. Each describes a different failure mode, so a healthy reading in one category doesn't prove that the whole service is healthy.
Bandwidth utilization and throughput reveal whether a link has enough capacity for current demand. For example, a 50-person office may saturate a 200 Mbps circuit at 9 a.m. during backups, software updates, and cloud activity. A sustained rise toward the circuit's limit is a warning sign, while a short burst may be harmless. Interface counters on a router or switch provide the first measurement, and flow data can identify which applications or hosts consume the capacity.
Latency measures the time required for traffic to travel and return, commonly called round-trip time. A voice call that adds 150 ms because traffic crosses an undersized VPN can feel delayed even when throughput looks adequate. Industry guidance commonly treats latency below 100 ms RTT as suitable for most applications, with path-specific baselines more useful than a universal rule. These practical thresholds are summarized in network performance monitoring guidance.
Packet loss records traffic that fails to reach its destination. A wireless link dropping 2% of packets during busy periods can cause retransmissions, slower transfers, and visible problems in real-time applications. Industry guidance commonly treats loss below 1% as broadly acceptable for many networks, while real-time traffic may need a target near 0.1%. A synthetic ping or endpoint test can measure loss between specific locations.
Jitter measures variation in packet arrival timing. A Teams call may sound choppy when average latency looks reasonable because packets arrive unevenly. For VoIP, jitter under 30 ms is commonly treated as acceptable, while values over 30 ms can produce choppy audio and values over 50 ms may make a call unusable, as explained in voice and video network testing guidance.
Availability shows whether a circuit, device, or critical service can be reached. A service can have high availability but poor user experience if it responds slowly, so availability should sit beside latency, loss, jitter, and throughput rather than replace them.
| Metric | What it tells you | Healthy range | Warning sign | Where to measure it |
|---|---|---|---|---|
| Bandwidth utilization | How much link capacity traffic consumes | Below the circuit's practical limit | Sustained saturation or recurring peaks | Router, switch, or flow collector |
| Latency | How quickly traffic travels and returns | Below 100 ms RTT for most applications | Rising response time or sluggish interactive work | Synthetic probe or endpoint |
| Packet loss | How much traffic fails to arrive | Below 1% for many networks, near 0.1% for real-time use | Retransmissions, freezes, or dropped calls | Path test, endpoint, or probe |
| Jitter | How consistently packets arrive | Below 30 ms for VoIP | Choppy voice or unstable video | Voice path probe or endpoint |
| Availability | Whether a target is reachable | Consistent reachability | Flaps, outages, or intermittent access | Device poll and synthetic test |
Teams should alert on percentiles and path-specific baselines where the platform supports them. Averages can hide brief congestion bursts that users still notice.
Common Monitoring Approaches and Tools
SMBs don't need every possible telemetry source on the first day. They need enough coverage to answer whether a problem is local, path-related, application-specific, or outside the organization.
SNMP polling queries routers, switches, firewalls, and other devices for interface traffic, errors, CPU, memory, and availability. It offers broad coverage and straightforward trend charts, but a polling interval can miss a short burst. It also shows device state more readily than the identity of the application causing congestion.
Flow data, including NetFlow, sFlow, and IPFIX, records traffic conversations. It can reveal that a backup server, video service, or software update is consuming a link. Flow data generally doesn't provide the full contents of packets, so it helps answer “who is using the link?” rather than every question about why a transaction failed.
Synthetic transactions actively test a user path on a schedule. A probe can check response time and loss between a branch office and a cloud service even when no employee has opened a ticket. This is valuable for internet and SaaS paths that internal device monitoring can't fully see.
Packet capture records traffic at a deeper level for forensic investigation. Tools such as Wireshark can help a skilled technician isolate protocol behavior, but packet capture demands more expertise, storage, and careful handling than most small businesses need for continuous use.
| Approach | What It Sees | What It Misses | Skill Level | Typical Cost |
|---|---|---|---|---|
| SNMP polling | Device health, interface usage, errors, and availability | Brief bursts and much of the user experience | Low to moderate | Open source or subscription options |
| Flow records | Traffic sources, destinations, applications, and volume | Full packet detail and some endpoint context | Moderate | Collector and platform licensing may apply |
| Synthetic tests | Experience across selected paths and services | Unmeasured paths and underlying device cause | Low to moderate | Usually subscription or platform based |
| Packet capture | Detailed packet behavior for deep diagnosis | Broad, economical coverage across a distributed estate | High | Open source tools exist, appliances and storage add cost |
A five-person office may begin with SNMP and a few synthetic tests. A 50-person, multi-site company may add flow data. An enterprise suite or full observability platform can make sense when hybrid cloud, many locations, and multiple operations teams create a larger investigation burden. Agentless monitoring avoids a resident process on production servers, while agent-based collection consumes ongoing CPU and memory, with overhead increasing as collection frequency rises. The trade-off is outlined in this comparison of agentless and agent-based monitoring.
Building a Monitoring Practice Step by Step
A small team can establish a useful practice over roughly one quarter without attempting to instrument everything at once. The priority is to create a reliable baseline, connect alerts to people, and document what happens after an alert arrives.
Start with inventory and normal behavior
During the first two weeks, list every router, switch, firewall, critical server, wireless controller, important endpoint group, internet circuit, site, and cloud dependency. Record ownership and business importance. A payroll system and a guest wireless network shouldn't receive identical alert severity.
During the next two weeks, collect a normal view of traffic and service behavior. The baseline should cover different working periods, because a school, factory, and multi-site office can have very different busy cycles. Guidance on threshold design recommends monitoring for two to four weeks before finalizing limits, so the team can account for normal variations across days and times. The recommendation appears in network monitoring metrics and protocol guidance.
Connect signals and create useful alerts
Enable SNMP or flow exports on the relevant switches and routers, deploy a collector, and build simple views for latency, packet loss, jitter, throughput, bandwidth utilization, availability, and errors. Alerts should have severity levels. A warning can identify a trend, while a critical alert should indicate likely user impact or loss of a business service.
Set alerts before the limit is reached. One practical approach is to alert at 80% to 90% of a service-level target, giving staff time to investigate rather than waiting for failure. For example, a 100 ms latency target can produce an early warning around 80 ms to 90 ms. The rule should be adapted to the measured path, not applied blindly.

Turn alerts into response
Write one-page playbooks for the three incidents most likely to disrupt the business. Each playbook should identify the first checks, the person responsible, the escalation contact, the evidence to capture, and the condition for closing the incident. A latency alert might prompt a path test, flow review, interface error check, and provider comparison.
Reserve a weekly review for trends and a monthly tuning pass for false positives. Teams should retire alerts that never lead to action, add coverage where incidents escaped detection, and document changes. Organizations that need help maintaining device inventories, alerting, and infrastructure documentation can review network infrastructure management services as one possible operating model.
Before week one, the owner or IT lead should confirm that device access is available, critical services are named, alert recipients are current, a collector location is approved, and someone has time to review notifications.
Measuring the Return on Monitoring Investment
An owner doesn't need to defend monitoring with abstract dashboard counts. The stronger case connects measured incidents with lost revenue, blocked staff time, recovery effort, and capacity decisions.
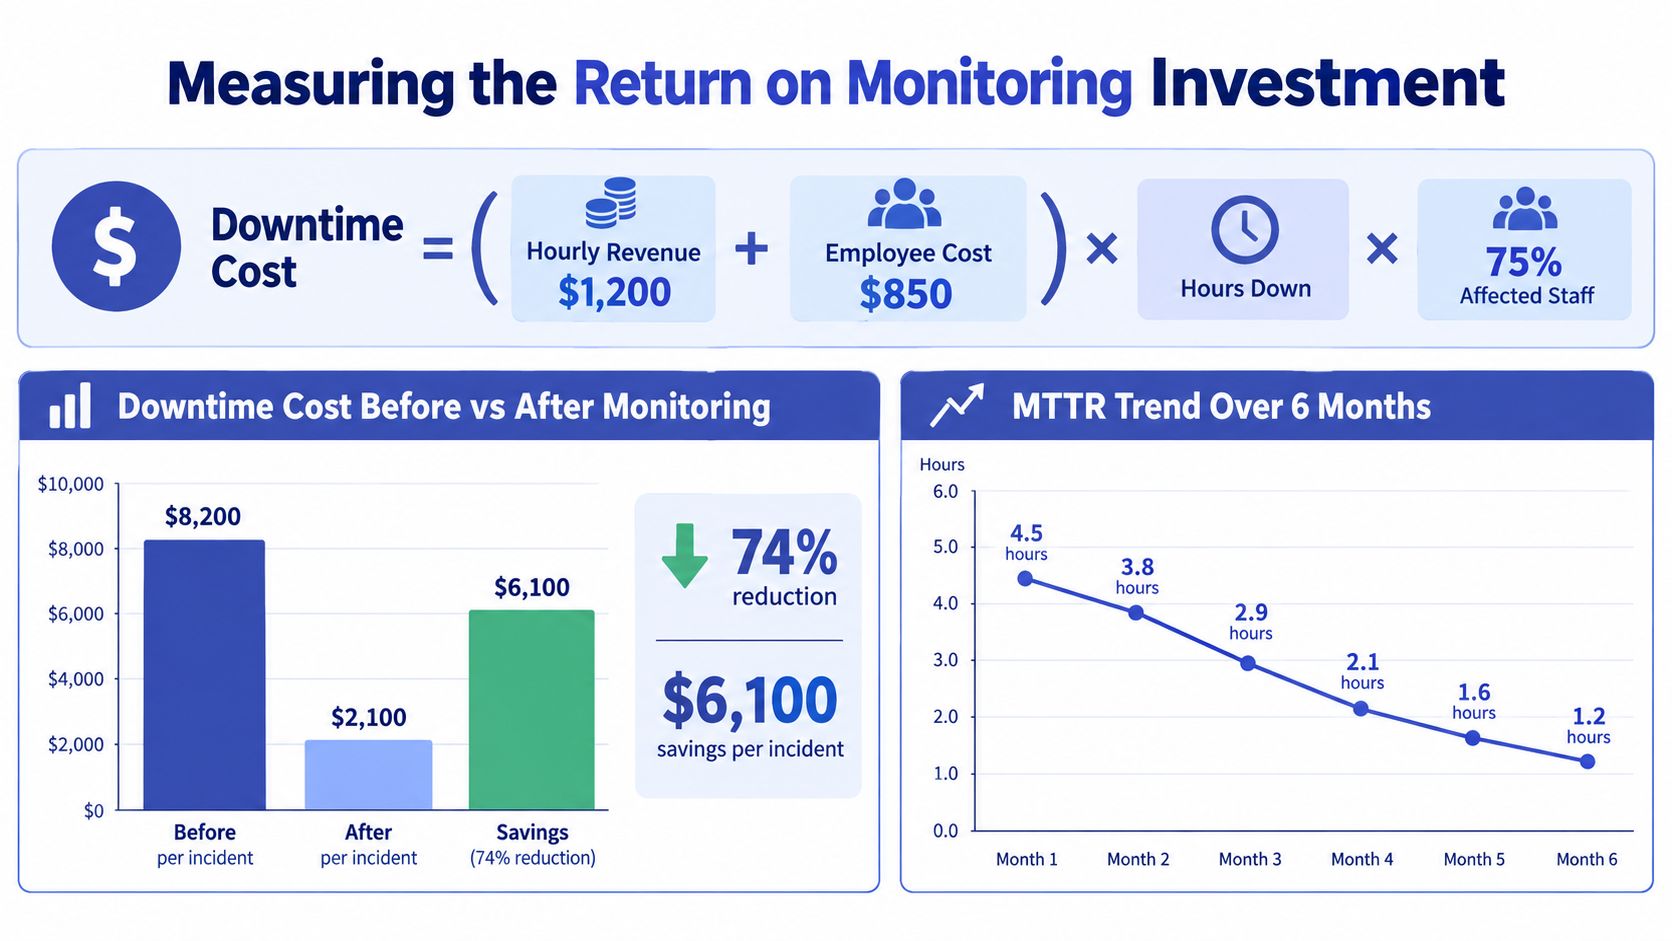
A simple downtime model starts with three inputs: hourly revenue, hourly employee cost, and the share of staff blocked by the outage. For example, a business can calculate a lost-work estimate from $1,200 in hourly revenue plus $850 in employee cost, multiplied by hours down and 75% affected staff, using the calculation shown in the monitoring return infographic. The example isn't a universal cost. It gives an owner a structure that can be replaced with the company's actual figures.
The same discipline applies to incident duration. The infographic presents a comparison of $8,200 per incident before monitoring and $2,100 after monitoring, a $6,100 saving and 74% reduction, along with an illustrative MTTR trend from 4.5 hours in month 1 to 1.2 hours in month 6. Those values belong to the visualization's worked example, not a promise that every business will achieve the same result.
Count avoided incidents carefully
Suppose a capacity alert identifies a saturated link while the business still has time to reschedule backups, change traffic priorities, or order additional capacity. The financial value comes from the outage that didn't occur, but the estimate should be conservative. Staff can compare the alert timestamp with utilization records, maintenance actions, incident history, and any customer or employee impact that would likely have followed.
A practical formula is:
Avoided incidents multiplied by average cost per incident, minus annual tool and labor cost.
The inputs should come from accounting records, payroll assumptions, ticket timestamps, provider credits, and monitoring history. If a figure is uncertain, the owner should label it as an estimate rather than present it as a measured saving. That honesty makes the calculation more credible during a budget review.
Budget test: Monitoring pays for itself only when the organization can connect an alert to a decision, a shorter incident, or a prevented disruption.
The market's direction also indicates that NPM is becoming a mainstream infrastructure category. One estimate values the global market at US$2.1 billion in 2021 and projects US$4.2 billion by 2031, implying a 7.1% CAGR from 2022 to 2031; another forecast projects US$2,145.70 million in 2026 to US$4,924.22 million by 2033, a 12.6% CAGR. These are independent market estimates, not an SMB's expected return, but they reflect growing demand for visibility across hybrid cloud and distributed environments, as documented in this network performance monitoring market estimate.
When to Outsource Monitoring to a Managed Provider
In-house monitoring offers direct control. Sensitive data can remain on local systems, the internal team can tailor thresholds closely, and changes don't depend on an outside queue. The cost is less visible but substantial, including tool licensing, collector maintenance, alert review, specialist training, and coverage outside normal working hours.
Managed services shift more of that work to a predictable service arrangement. A provider can watch availability, bandwidth, latency, and alerts continuously, then follow an agreed escalation process. The business still needs ownership and decision-making, but it doesn't have to build every monitoring skill internally. The managed network service provider model offers one example of how that responsibility can be structured.
| Factor | In-House Monitoring | Managed Services |
|---|---|---|
| Cost | Tools, staffing, training, and maintenance remain internal | Fees are more predictable, with monitoring labor included in the service |
| Coverage | Depends on internal schedules and staffing | Can provide continuous oversight under an agreed scope |
| Expertise | Builds organizational knowledge over time | Adds access to network and incident-response skills |
| Control | Direct access to systems and configuration | Shared control through defined permissions and escalation |
| Risk | Missed alerts or skill gaps remain the business's responsibility | Provider quality, scope, and communication must be managed |
A straightforward decision rule helps. If the business has fewer than three IT staff, operates more than one site, depends on uptime for revenue, or has already experienced an unexplained slowdown, a managed partner usually delivers faster value than recruiting and training for every requirement. This isn't an absolute rule. A mature internal team with strict data residency requirements and existing tooling may reasonably extend its current platform.
Before transferring responsibility, the business should inventory devices, document current thresholds, define escalation paths, confirm access boundaries, and agree on reporting cadence. The provider should also explain how it handles false positives, maintenance windows, provider outages, and incidents that cross cloud or ISP boundaries. Visibility matters most where the business has the least control, especially across public cloud and internet paths. A 2026 network operations report found 95% of leaders reported poor visibility into key network segments, 87% reported internet and cloud blind spots, and 95% wanted more transparency from ISPs, according to the 2026 network operations report.pdf).
Putting It All Together and Next Steps
A dependable network doesn't require an enormous operations center. It requires a habit of measuring the paths and services that matter, reviewing abnormal behavior, and assigning a person to act when the evidence points to a problem.
Five decisions keep the practice focused:
- Monitor before trouble starts. Early signals create more options than user complaints do.
- Start with the core measures. Latency, packet loss, jitter, bandwidth, throughput, availability, and errors expose different problems.
- Match the method to the team. SNMP and synthetic tests may suit a small office, while flow data and managed support become more useful as sites and dependencies grow.
- Trust baselines over blind defaults. Normal behavior differs by path, schedule, and service, so thresholds should reflect observed conditions.
- Measure business value. Avoided downtime, shorter incidents, and reclaimed employee time make the investment understandable.
This week, an internally managed environment should confirm that one critical device is being watched and that one meaningful alert reaches the correct phone. A business considering outside help should book a discovery call and prepare a short inventory of sites, circuits, firewalls, switches, critical applications, and recent incidents.
Monitoring isn't a purchase that finishes the work. It's an operating habit that helps a small team replace assumptions with evidence and respond before a minor performance change becomes a business interruption.
Nutmeg Technologies provides managed IT services with proactive monitoring, maintenance, and strategic oversight for organizations that need more predictable technology operations. To discuss network performance monitoring, co-managed support, or a fully outsourced approach, visit Nutmeg Technologies.